Google releases EmbeddingGemma 2, one open model for five media types
Google released an open model on the 6th of October that finds related text, code, images, video and sound.
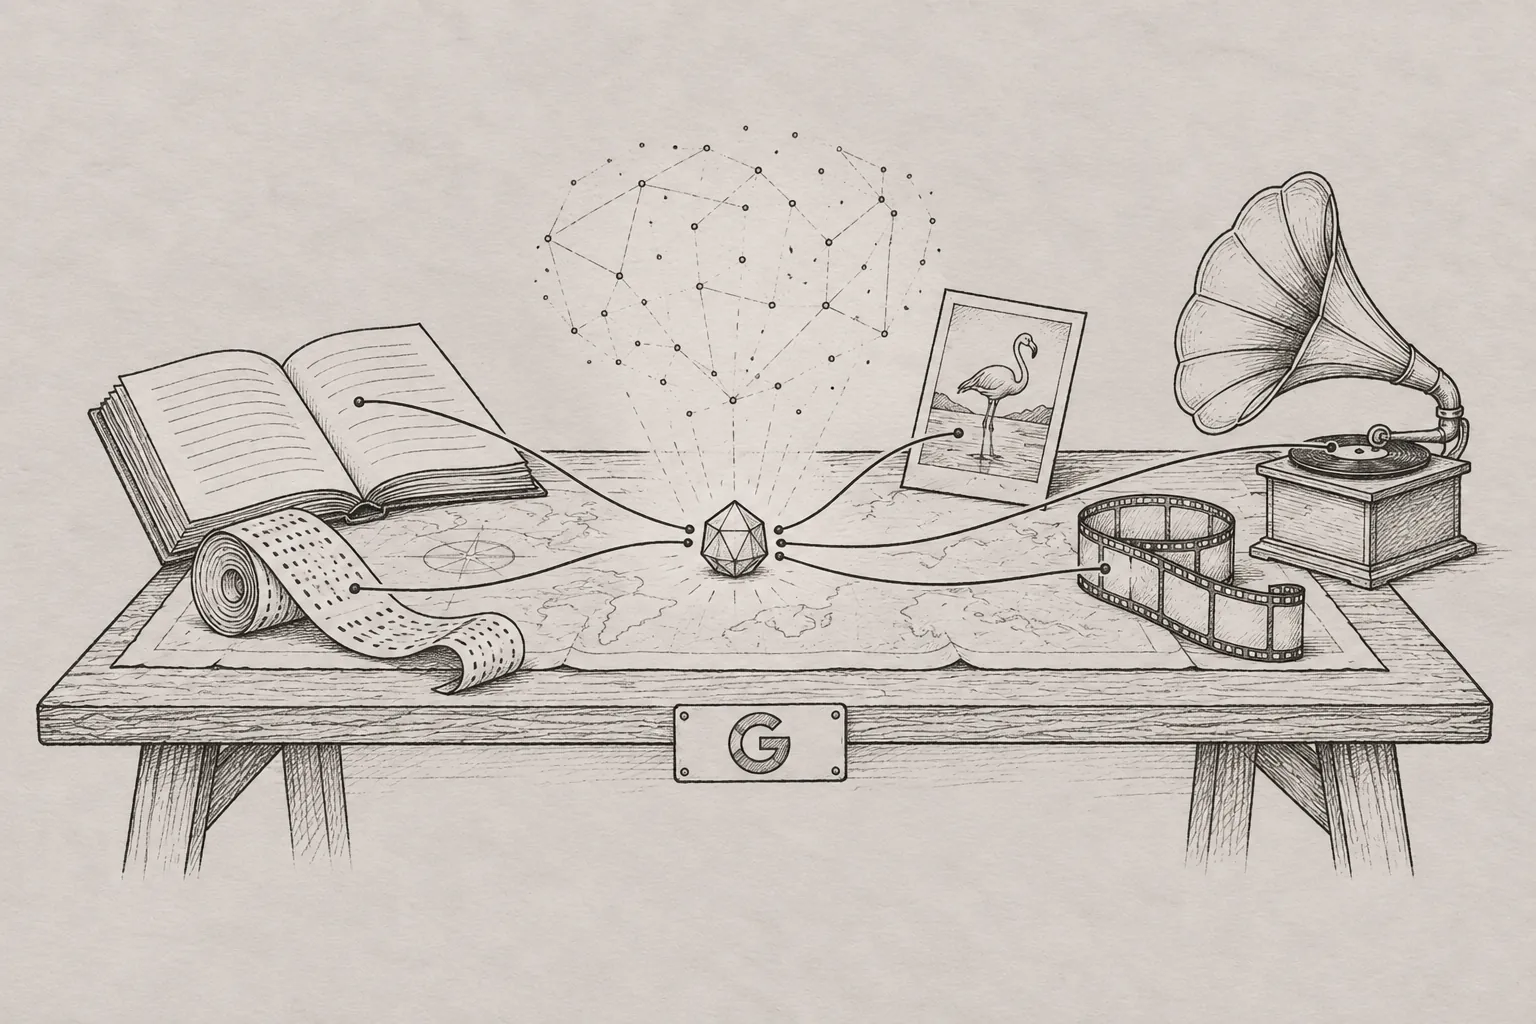
Google released EmbeddingGemma 2 on the 6th of October 2026, according to the Google Developers Blog. The open model works with text, computer code, images, video and audio.
Anyone can download it from Hugging Face under the Apache 2.0 licence, the post says.
Why it matters
An embedding model turns content into a list of numbers. Search systems compare those lists to find related items.
One model now handles all five kinds of content. In Google's diagram, a flamingo photo, a flamingo video and a sentence about flamingos sit close together.
Key facts
The full model has 740 million parameters, the values a model learns in training, the post says. Its parts can be loaded one by one.
The smallest part, for text and code only, has 270 million.
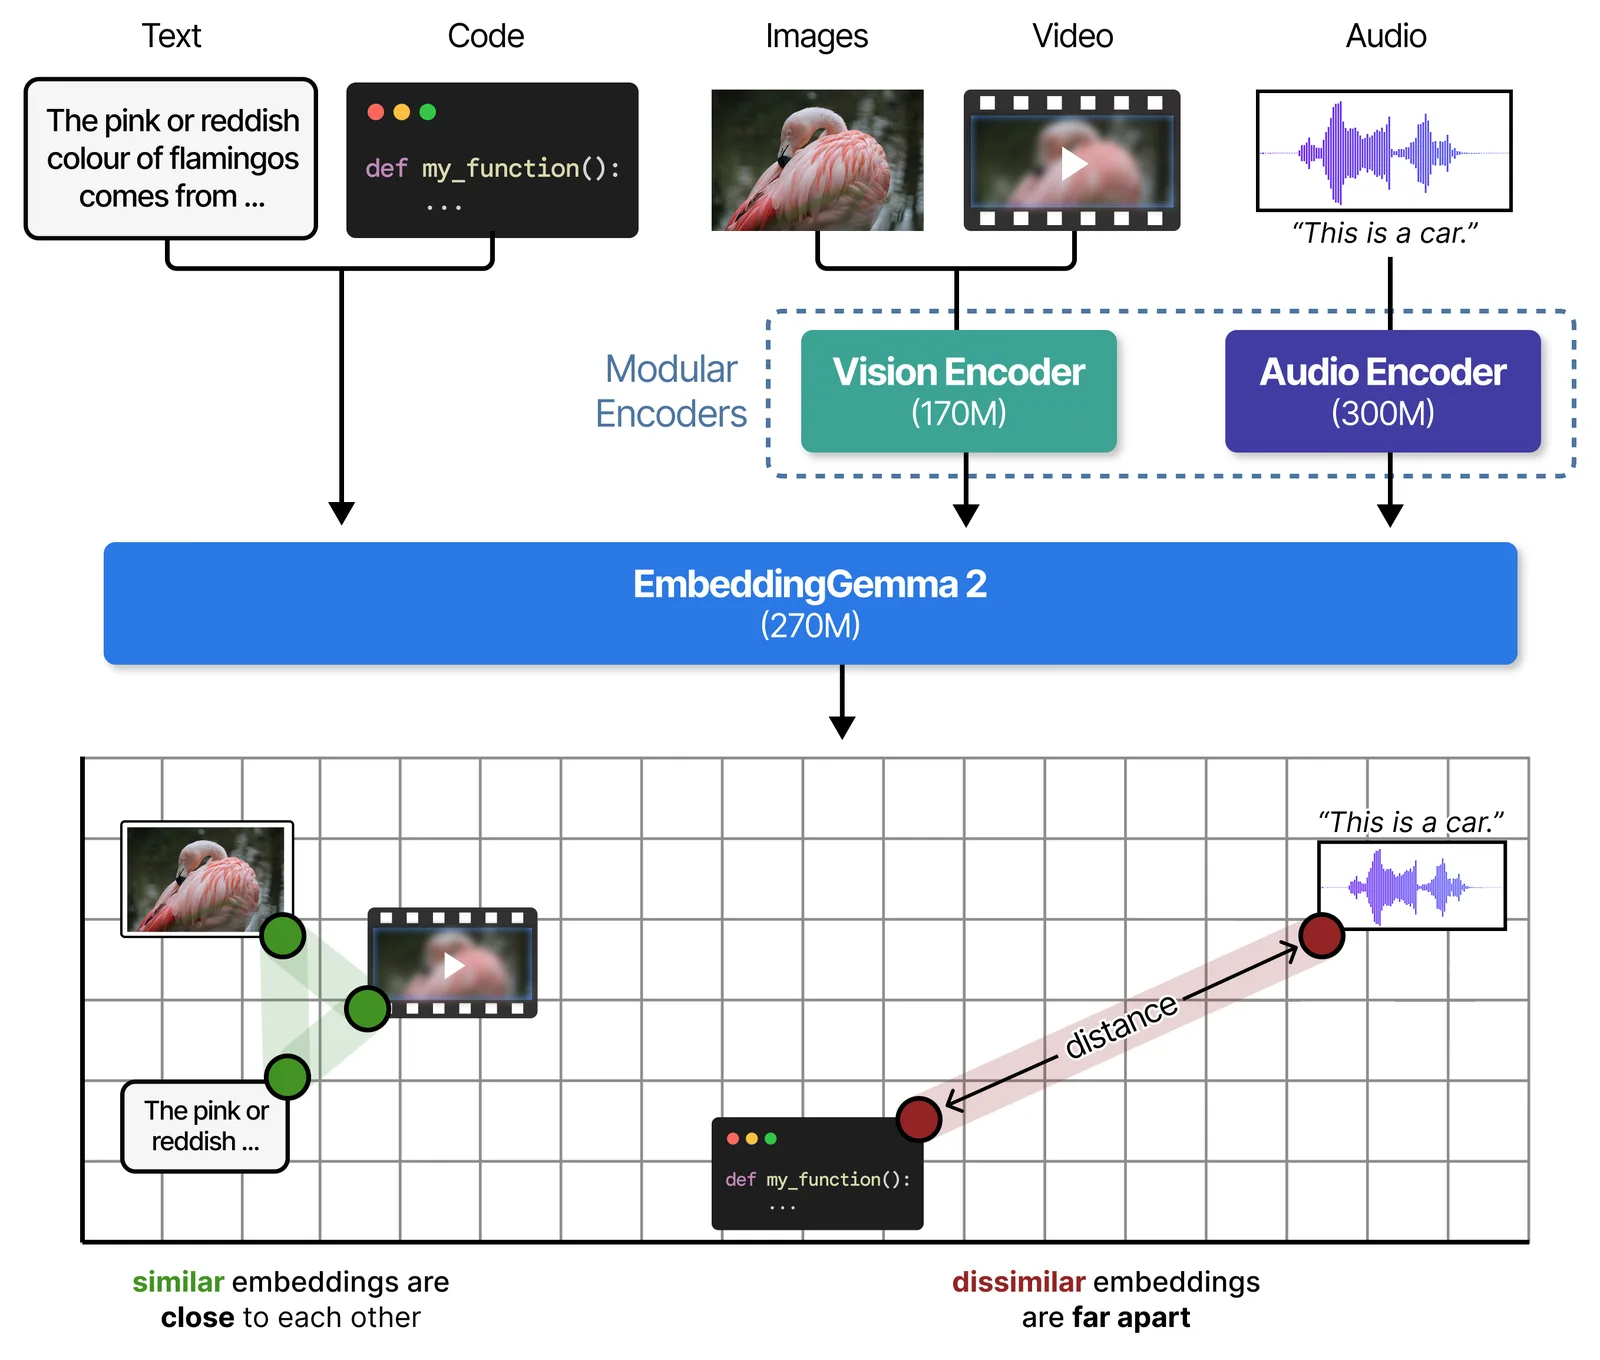
Users can shorten each list of numbers to save space. A million full lists take about 1.5 gigabytes, against about 250 megabytes at the shortest size, Google wrote.
At that shortest size, image, video and speech search keep about 75 percent of their quality, the post says.
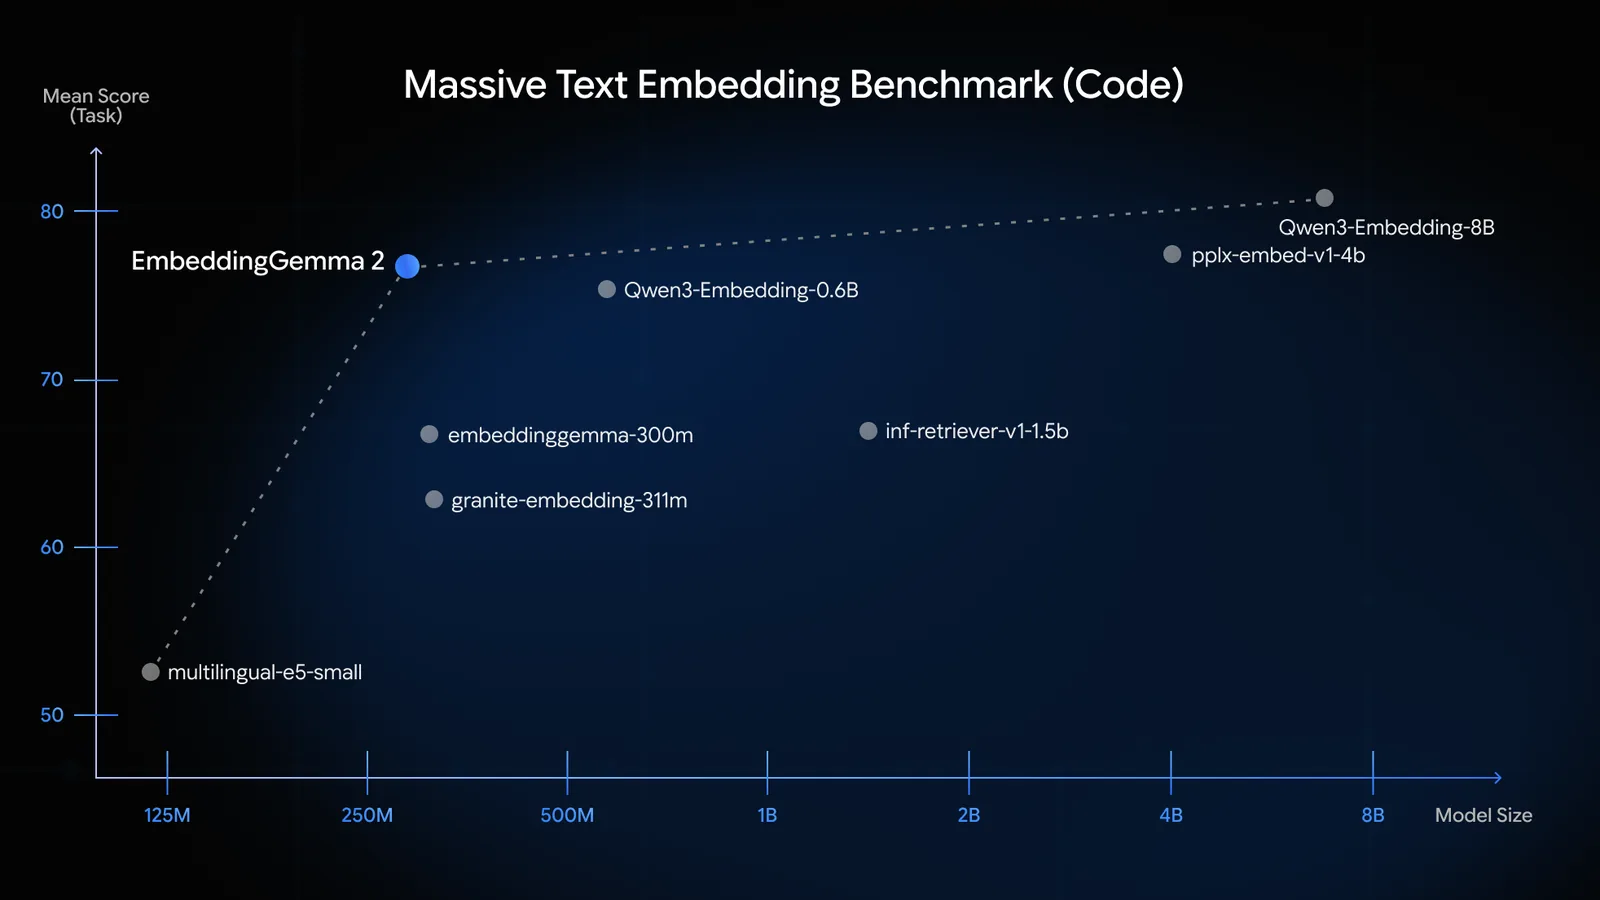
On code, the model scores 14 percent higher than the first version, Google said. The test is a public one called the Massive Text Embedding Benchmark.
What's next
The model already runs in tools such as Ollama, LM Studio and Hugging Face Transformers, the post says. Google suggests letting an AI agent search a codebase on the user's own computer.