Microsoft Maia 300: 40% more tokens per MW
Microsoft announced its Maia 300 AI chip on the 12th of October 2026, with deployments from 2027. It says the chip makes 40% more AI text per unit of power than leading GPU systems.
 Microsoft's Maia 300 AI chip
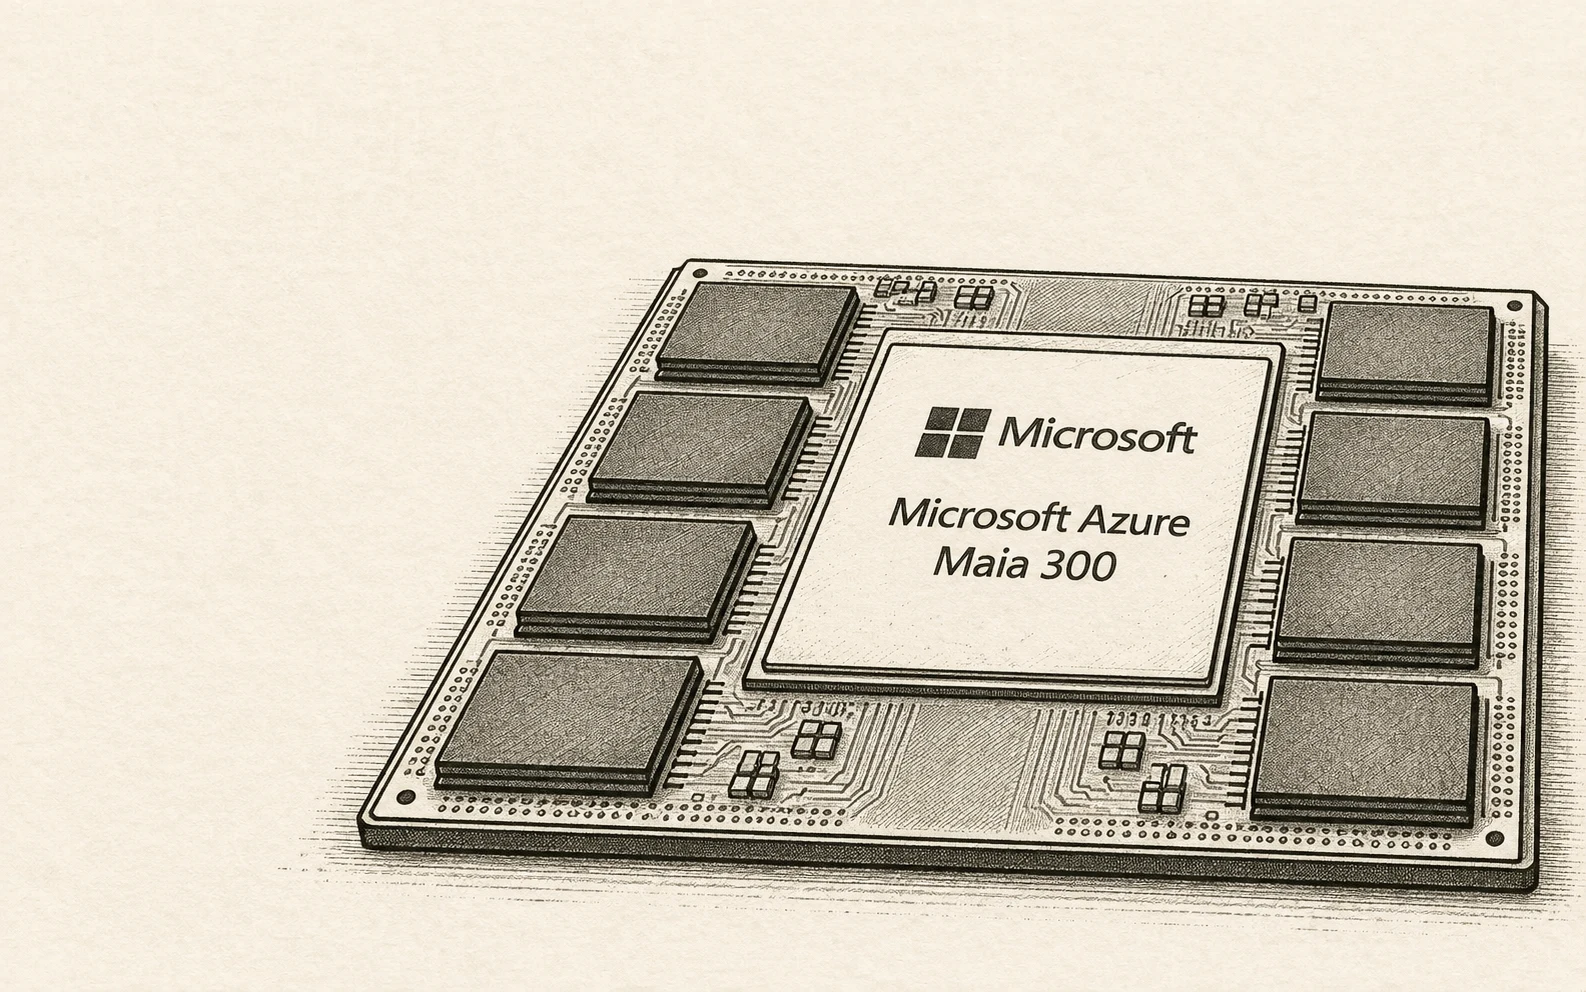
Microsoft expects its Maia 300 AI chip to make 40% more tokens per megawatt than leading GPUs, the graphics chips most AI runs on. Its cloud chief Scott Guthrie said so in a blog post on the 12th of October 2026.
Tokens are small pieces of text an AI model reads and writes. Microsoft said Maia 300 production deployments begin in 2027, when the Maia family grows to several gigawatts.
Maia 300 racks hold 96 chips in 167 kilowatts
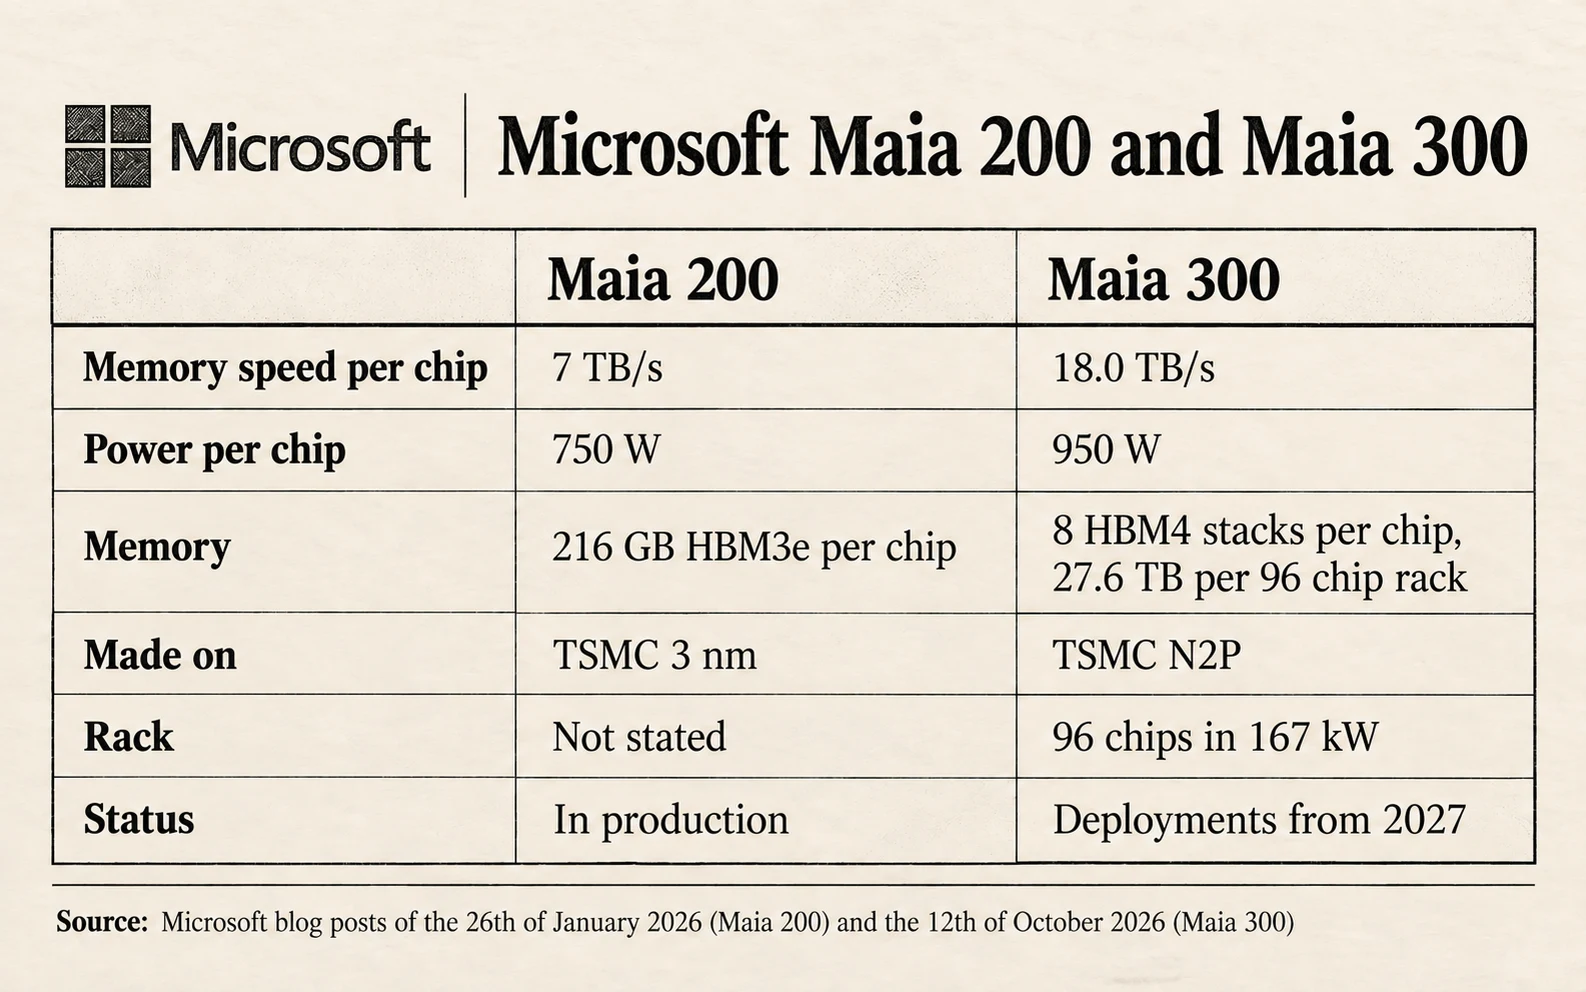
Each Maia 300 rack holds 96 accelerators, chips built to run AI models, within 167 kilowatts, the post said. A full rack gives up to 7 times the token output of a Maia 200 rack.
Each chip has eight stacks of HBM4, fast memory beside the chip, at 18 terabytes per second. The chip uses 950 watts, and its compute parts are made on TSMC's N2P chipmaking process.
Below we break down Maia 300 against Maia 200, from Microsoft's two posts
Maia 200 had 216 gigabytes of memory at 7 terabytes per second and used 750 watts, Microsoft's post of the 26th of January 2026 said.
So Maia 300 moves data 2.6 times as fast and draws 27% more power, by our arithmetic. Its rack holds 27.6 terabytes of memory, about 288 gigabytes per chip if spread evenly, by our arithmetic.
One gigawatt would feed about 6,000 Maia 300 racks, or 575,000 chips, by our arithmetic. That count leaves out cooling and other building power.
What is confirmed and what is still open
The 40% figure is Microsoft's own forecast. The post does not name the GPU systems used for the comparison.
The 7 times figure compares whole racks, and the post gives no Maia 200 rack size. The post cites no outside tests of Maia 300.
Maia 200 is in production and serves Microsoft Copilot
Maia 200 is in production, serves Microsoft Copilot and is deploying in the US, Europe and Australia, the October post said. GitHub Copilot and Microsoft Foundry are due to follow by the end of 2026.
Key facts
Announced by Microsoft on the 12th of October 2026.
40% more tokens per megawatt than leading GPU systems, by Microsoft's forecast.
96 chips per rack in 167 kilowatts, up to 7 times Maia 200 rack output.
Production deployments start in 2027.
Source: The Official Microsoft Blog, post by Scott Guthrie of the 12th of October 2026