Microsoft's MAI-Base-2: 2.8T in 38 days
Microsoft AI described MAI-Base-2 on the 15th of October 2026, a model with 2.8 trillion parameters trained in 38 days. It has no public release yet, and Microsoft plans to license it to partners.
 Microsoft AI's MAI-Base-2, 2.8T
Microsoft AI trained a model with 2.8 trillion parameters on 16,000 GPUs in 38 days, it wrote on the 15th of October 2026. Parameters are the values a model learns in training.
The model, MAI-Base-2, is still in post-training and has no public release, Microsoft AI said in a Lab Notes post. It plans to license the weights to trusted partners through its Foundry service.
Microsoft AI says MAI-Base-2 needs 4 to 12 times less compute than DeepSeek
MAI-Base-2 is "4-12x more pre-training FLOPs-efficient" than DeepSeek-V4-Pro-Base, the post says. FLOPs count the math a computer does in training.
The detailed range on the same page is 4.2 to 12.3 times. Against Microsoft's own MAI-Base-1, the gain is 6.3 to 12.7 times, the post says.
The post gives no benchmark scores. It says MAI-Base-2 "outperforms every open-weight model we tested on our held-out evaluations."
Those tests included Moonshot AI's Kimi K3 and Alibaba's Qwen3.8, the post says. Microsoft AI notes that it compared only their post-trained versions.
Below we break down the training run: 50 trillion tokens, 14.6 million GPU hours
MAI-Base-2 read a mix of 50 trillion tokens, the small pieces of text a model learns from, Microsoft AI said. Its data stops in March 2026.
Data that pairs pictures with text made up 18% of the mix, the post says. Unique data grew about 36% over MAI-Base-1.
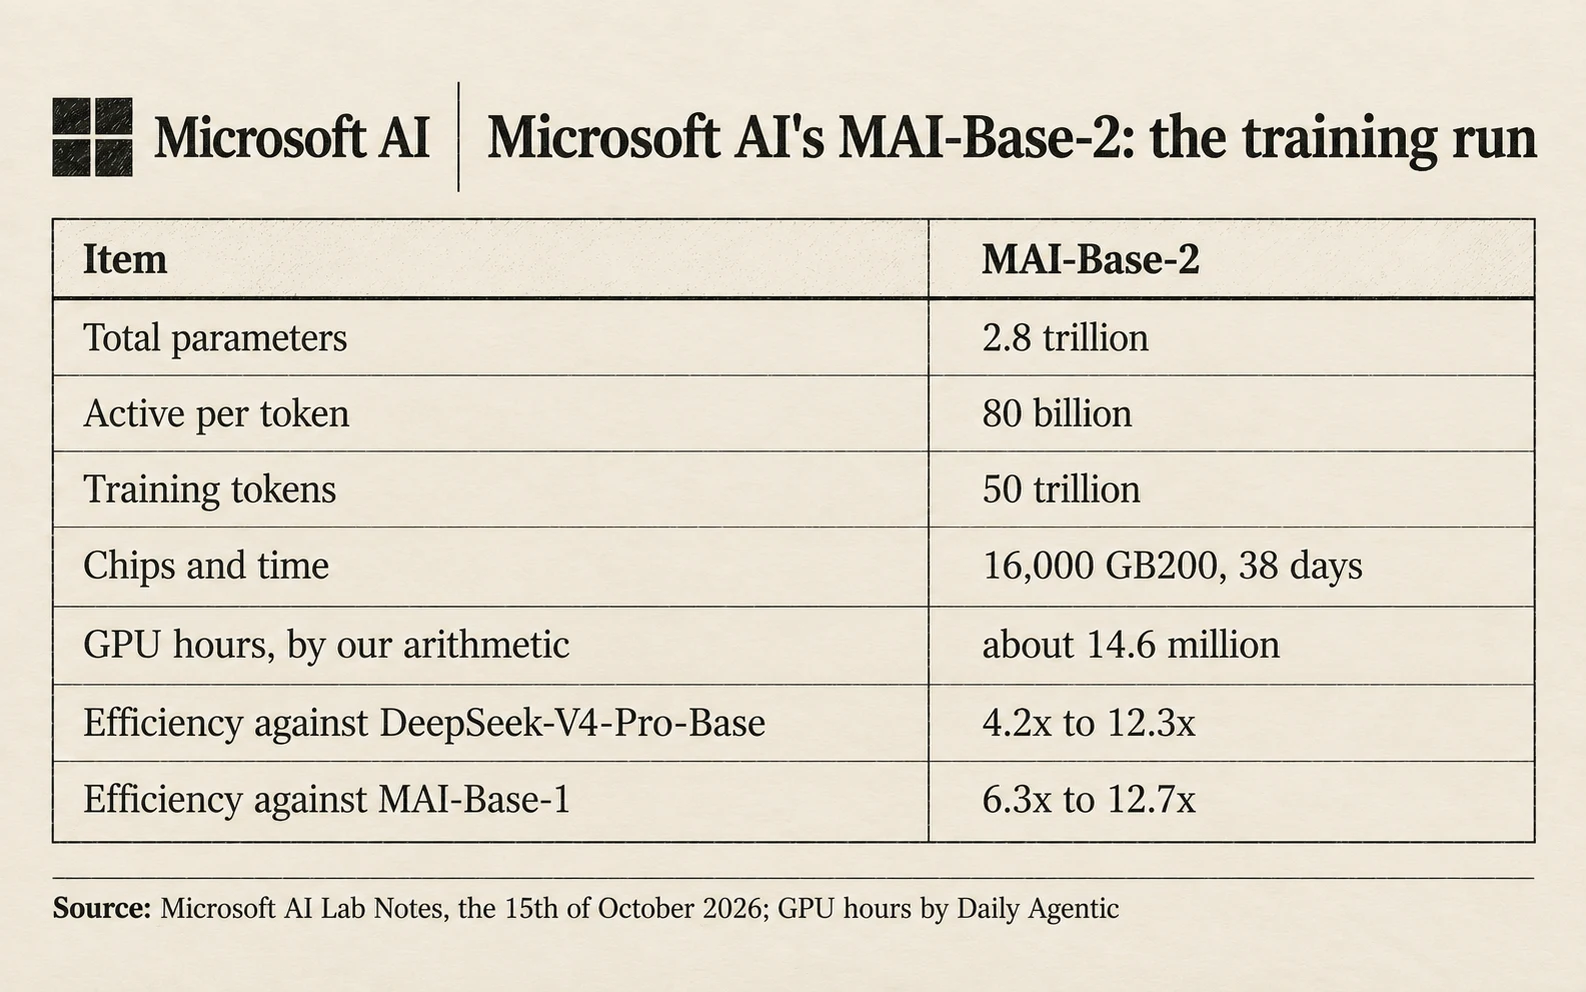
The run used 16,000 Nvidia GB200 chips in August and September 2026. That is about 14.6 million GPU hours, by our arithmetic.
Only 80 billion parameters work on each token, a design called mixture of experts. That is about 2.9% of the model at a time, by our arithmetic.
What is confirmed and what is not
All figures come from Microsoft AI's own post, which names no author. Microsoft AI gave no release date and no license terms.
The training data is organic and "does not involve distillation from other models," the post says. Distillation means training on another model's answers.
Key facts
Microsoft AI's Lab Notes post, the 15th of October 2026.
2.8 trillion parameters, 80 billion active per token.
16,000 GB200 chips for 38 days.
4 to 12 times more efficient than DeepSeek-V4-Pro-Base, Microsoft AI says.
Weights to go to trusted partners through Foundry, no date given.