Nanbeige free AI beats Qwen on 7 of 8 tests
Nanbeige released a free AI model called Nanbeige4.3-33B on Hugging Face on the 24th of October 2026. It beat Alibaba's Qwen3.8-27B on 7 of 8 coding agent tests, by Nanbeige's own scores.
 Nanbeige's free Nanbeige4.3-33B model
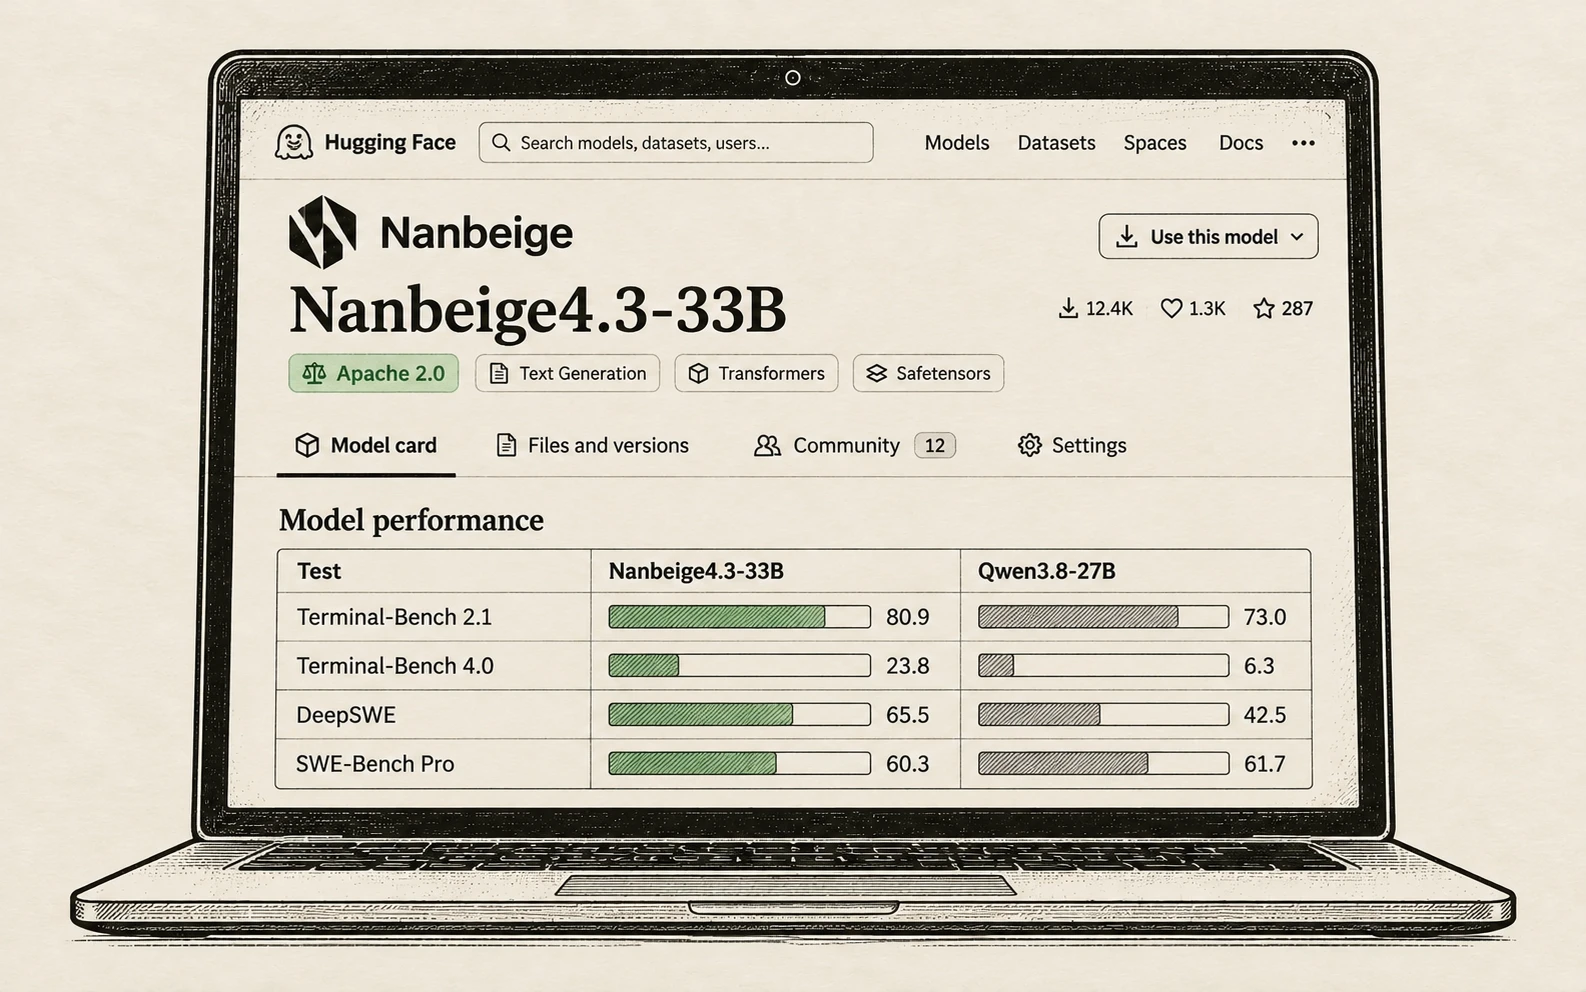
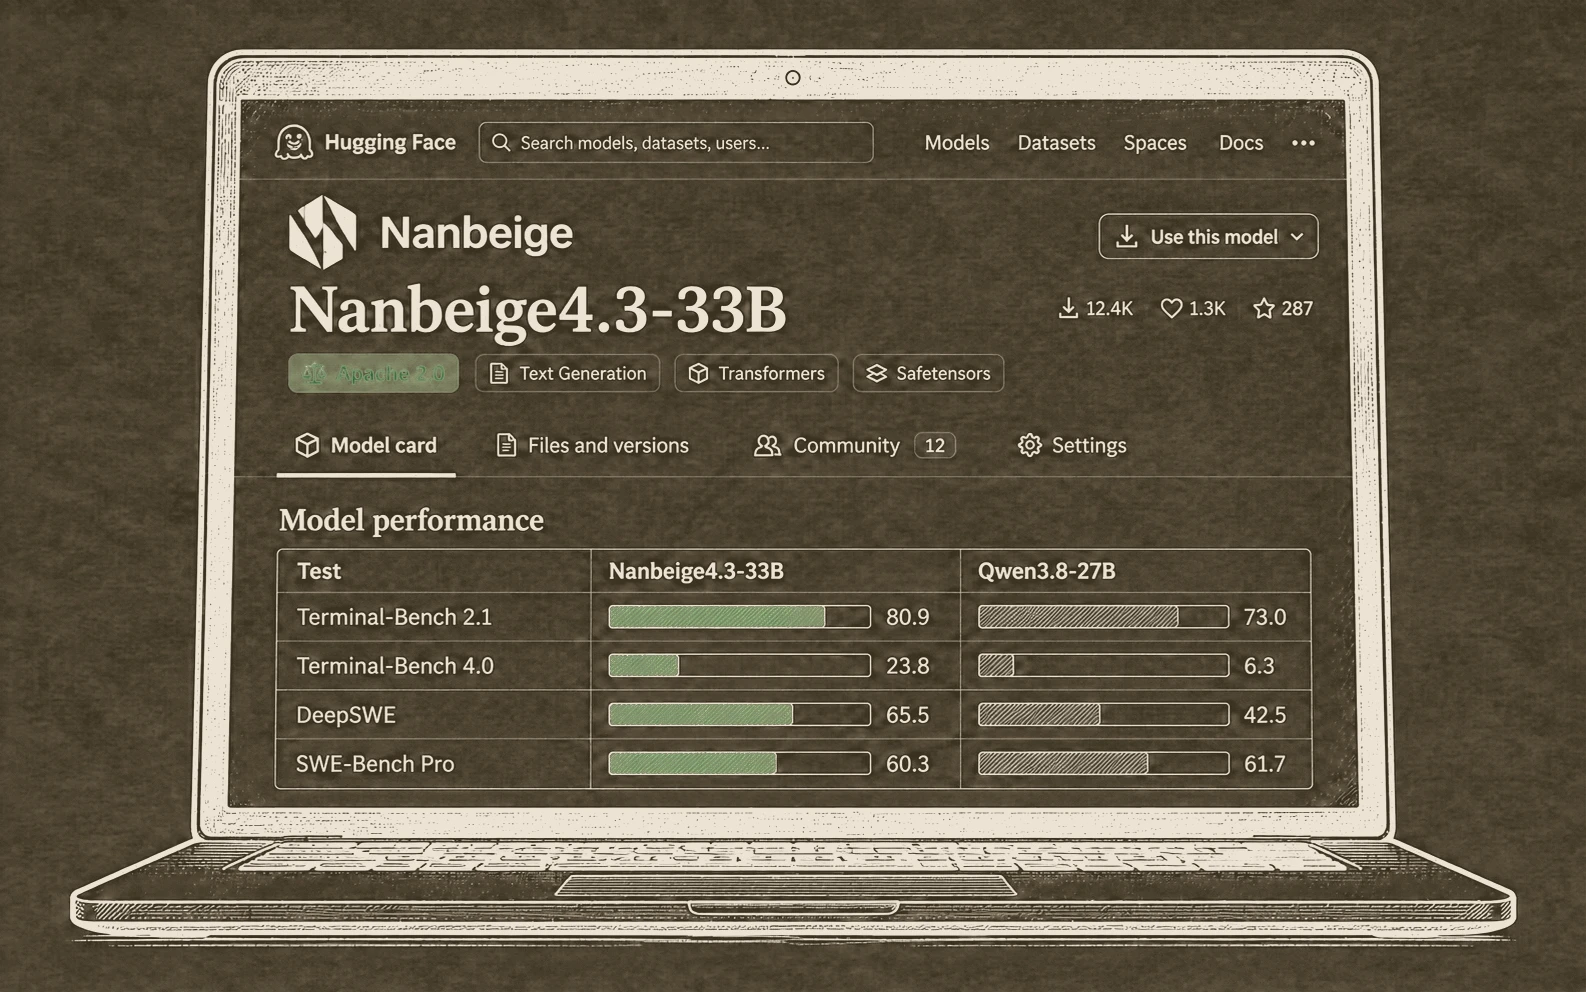
Nanbeige released a free AI model called Nanbeige4.3-33B on Hugging Face on the 24th of October 2026. It beat Alibaba's Qwen3.8-27B on 7 of 8 coding agent tests, Nanbeige's own model page shows.
Nanbeige is an AI team at Kanzhun, the Chinese firm behind the job app BOSS Zhipin. The model uses the Apache 2.0 licence, which lets anyone use it for free, even in business.
What Nanbeige4.3-33B is
The model has 33 billion parameters, the settings a model learns in training. Its weights, the files that make up the model, can be downloaded and run on your own computers.
Nanbeige calls it a "teacher" model whose skills it will pass to smaller ones, such as a planned 3 billion version. It can read up to 524,288 tokens at once, small pieces of words.
Scores on 8 coding agent tests
On DeepSWE, a test of fixing real software, it scored 65.5 against Qwen's 42.5, Nanbeige wrote. On Terminal-Bench 2.1, a test of work in a command window, it scored 80.9 against 73.0.
It lost only on SWE-Bench Pro, with 60.3 against Qwen's 61.7.
Scores on office agent tests
On Automation Bench, a test of office tasks done by an agent, it scored 54.2 against 38.3. It lost on GDPval, a test of real job tasks, with 84.8 against 86.4.
Below we break down the lead
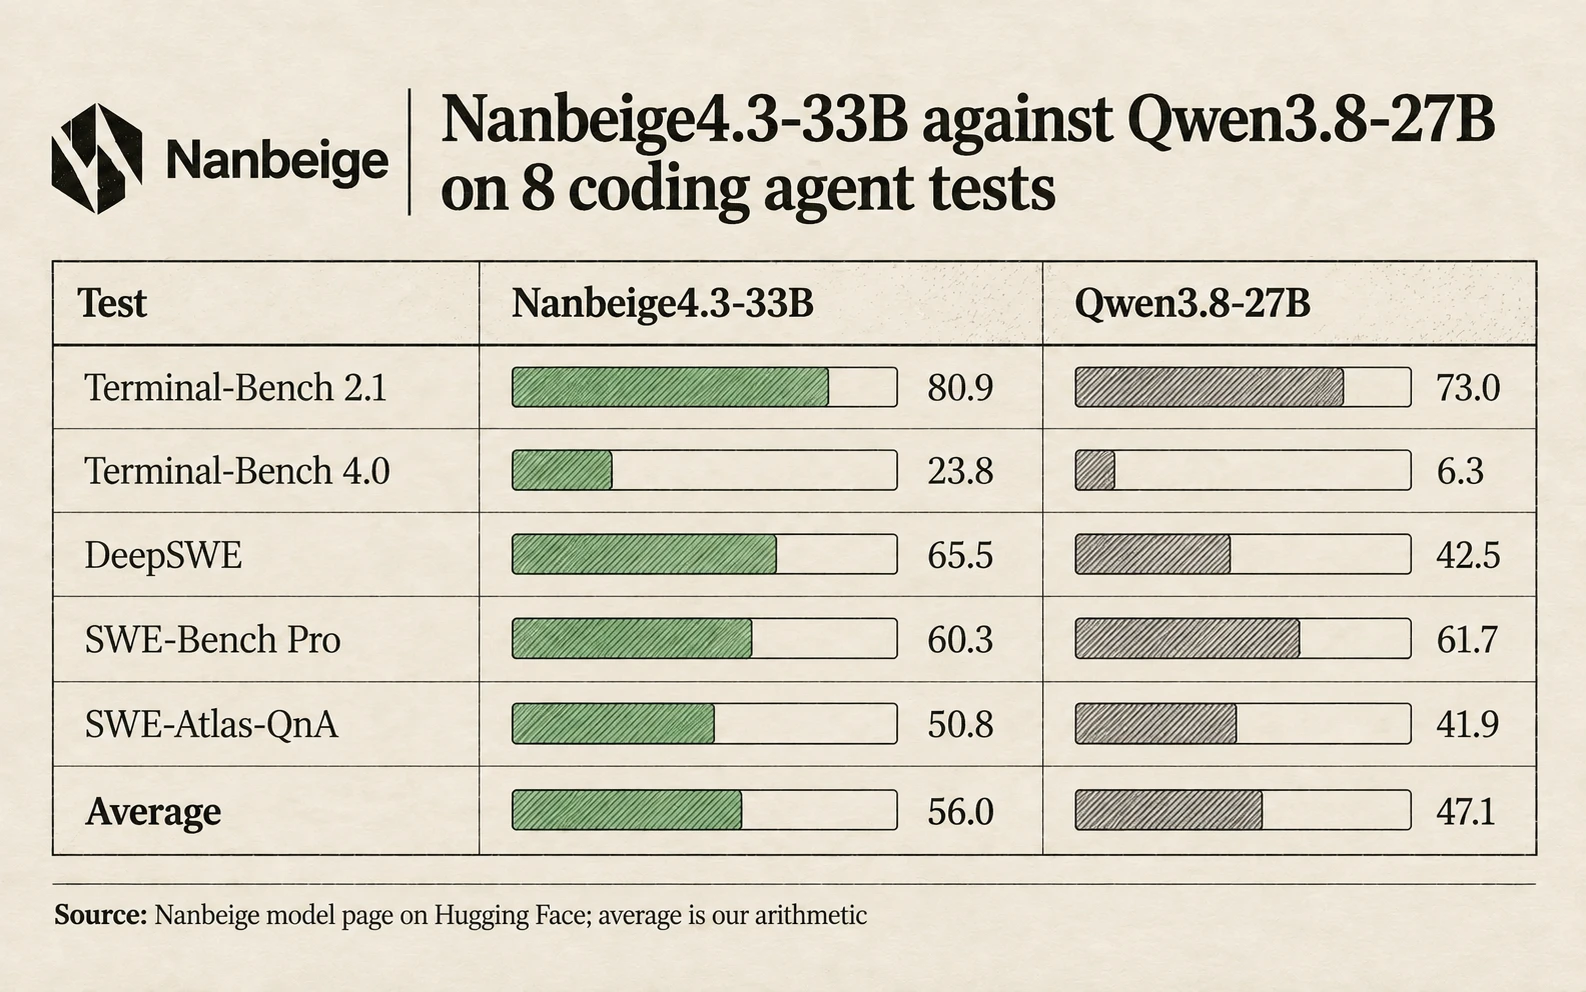
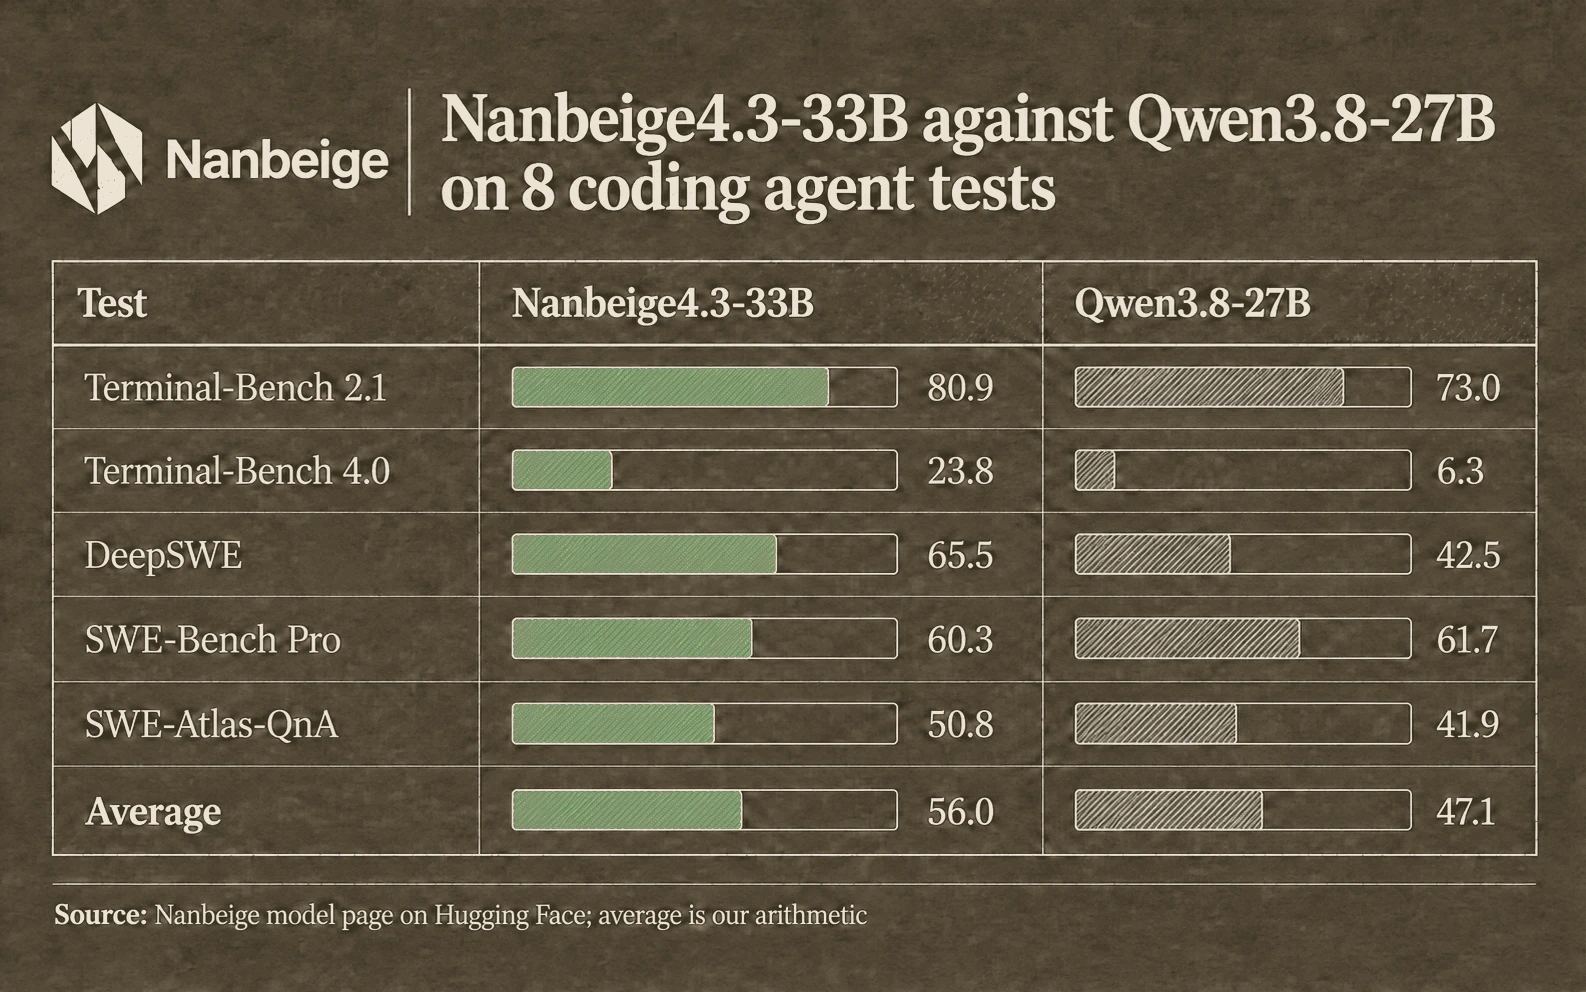
Across the 8 coding tests, Nanbeige4.3-33B averaged 56.0 and Qwen3.8-27B averaged 47.1, by our arithmetic. That is a lead of 8.9 points.
What is confirmed and what is not
All scores come from Nanbeige's own runs, with the same settings for each model, the page says. We found no outside check of the scores yet.
Key facts
Nanbeige released the model on the 24th of October 2026.
It has 33 billion parameters.
It is free under the Apache 2.0 licence.
It beat Qwen3.8-27B on 7 of 8 coding agent tests.
Source: Nanbeige, Nanbeige4.3-33B model page on Hugging Face